
On this page · 9 sections
- 01How Google indexing works: discovery, crawling, rendering, indexing
- 02Why Google doesn't index everything, or not quickly
- 03How long indexing takes and what affects it
- 04How to check if a page is indexed
- 05How to get a new page indexed
- 06How to get an updated page re-crawled
- 07Common 'not indexed' statuses and what they mean
- 08Why indexing now decides eligibility for Google's AI Overviews and AI Mode
- 09Every guide in this series
You can't force the timeline, but you can remove blockers, send clear signals and check what Google actually saw. It's worth the effort: Google still sends about 9 in 10 of the visits that search engines send to websites worldwide (StatCounter, September 2026), and its AI Overviews and AI Mode are built on the same index. That makes indexing in Google the first step for both classic rankings and Google's AI answers. This guide covers how search engine indexing works, why pages stall, how long it takes, and how to get new and updated pages indexed.
How Google indexing works: discovery, crawling, rendering, indexing
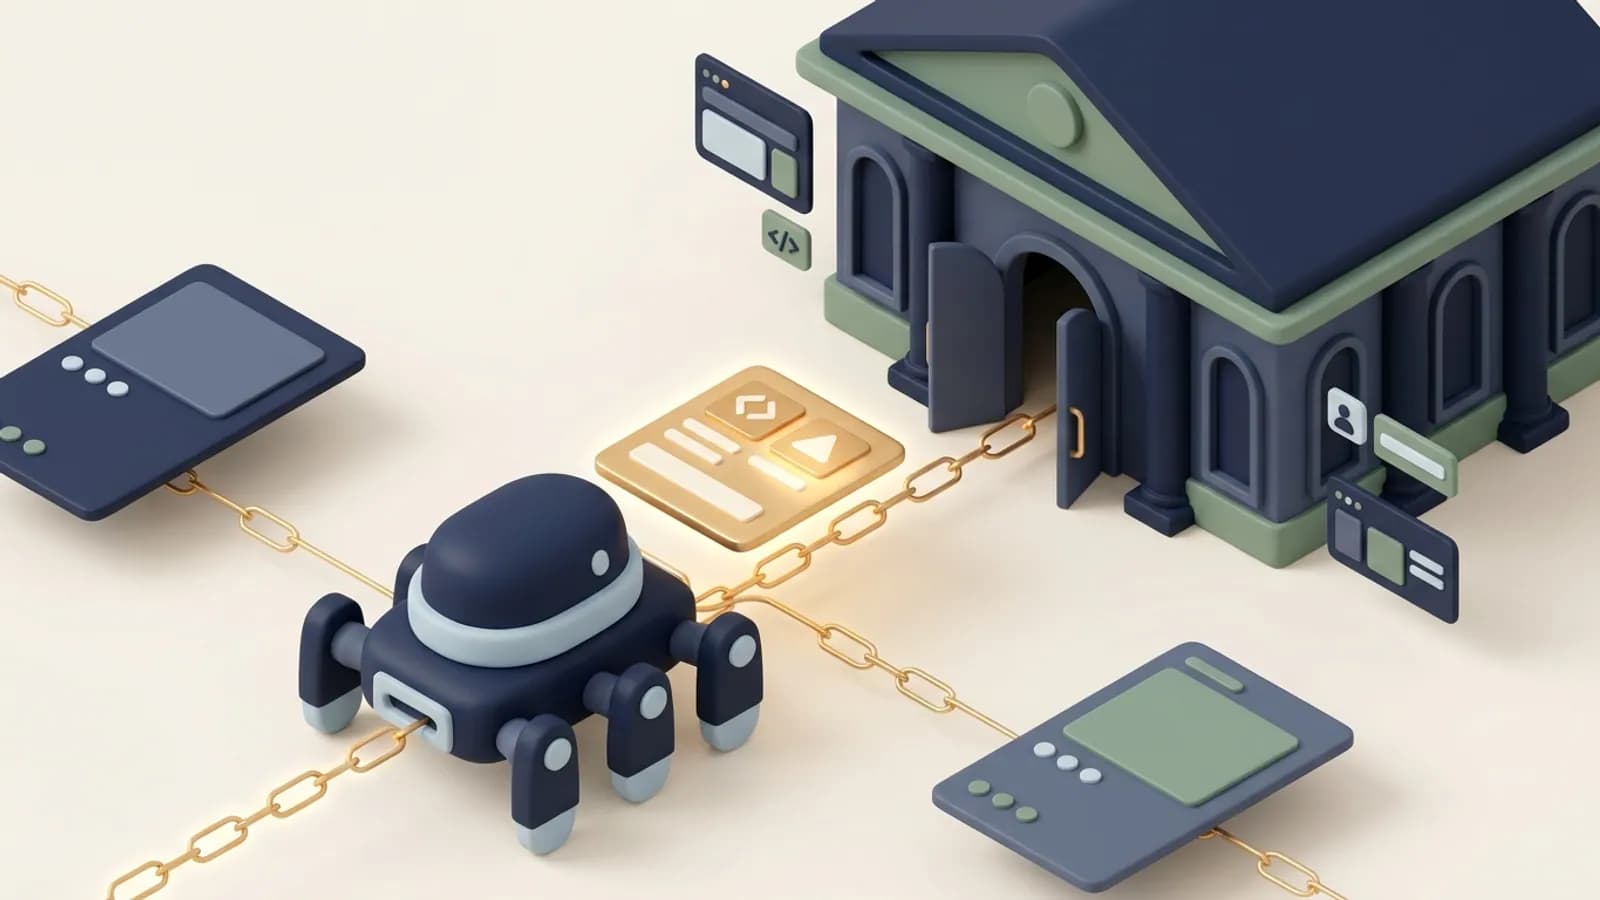
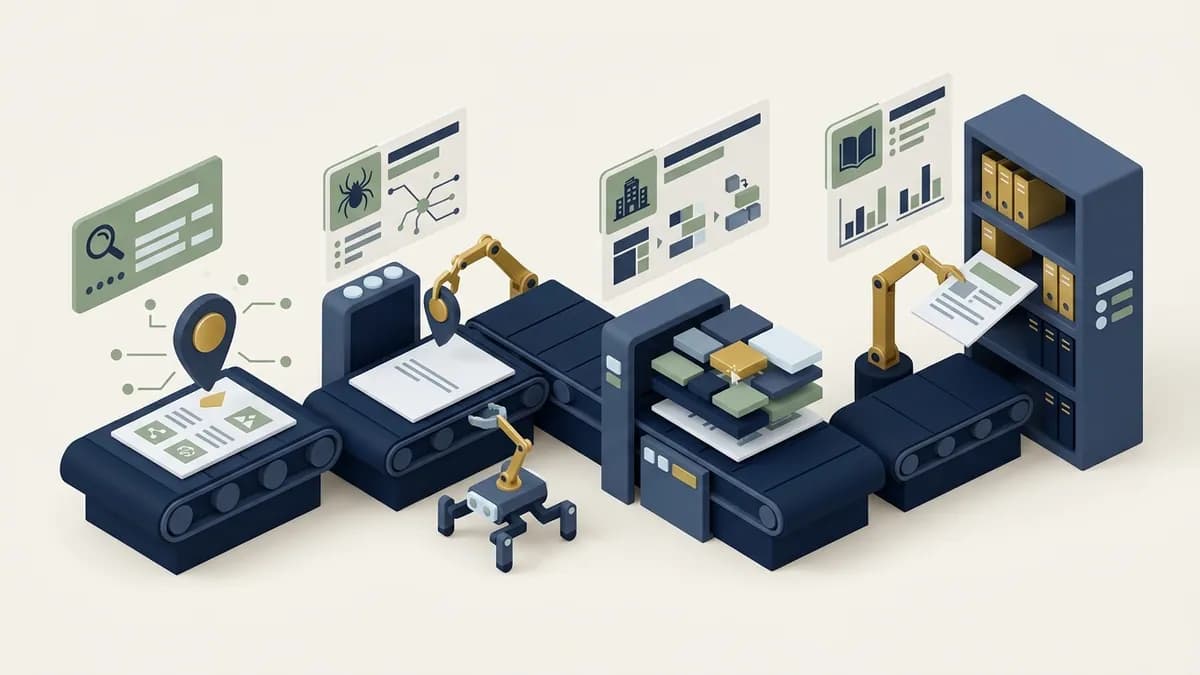
Google indexing works in four stages: Google finds a URL, fetches it, renders it like a browser, then decides whether the page is worth adding to its index. Google describes the same pipeline in How Search works.
Stage | What happens | Where it commonly fails |
|---|---|---|
Discovery | Google learns the URL exists, from links on pages it already knows, from sitemaps or from a submission | Orphan pages with no internal links; URLs missing from the sitemap |
Crawling | Googlebot requests the URL and downloads the response | robots.txt blocks, server errors, slow responses, crawl postponed |
Rendering | Google runs the page's JavaScript to see the final content | Content that only appears after user interaction or blocked resources |
Indexing | Google analyzes the content, picks a canonical and decides whether to store it | |
Two points are easy to miss. First, discovery is not crawling: Google can know a URL for weeks without fetching it. Second, crawling is not indexing: Google can fetch a page, read it and still decide not to keep it. The Search Console statuses "Discovered - currently not indexed" and "Crawled - currently not indexed" map exactly to those two gaps.
Why Google doesn't index everything, or not quickly
Google doesn't index everything because it has limited crawl capacity and a quality bar. Its systems choose which URLs to crawl, how often, and which crawled pages are worth storing.
Google's crawl budget guide breaks crawling into two parts:
- Crawl capacity limit: how much crawling your server can handle. If the site slows down or returns errors, "the limit goes down and Google crawls less."
- Crawl demand: how much Google wants to crawl. It depends on perceived inventory, popularity ("URLs that are more popular on the Internet tend to be crawled more often") and staleness.
Then comes the indexing decision. Common reasons a crawled page isn't stored:
- It's a duplicate or near-duplicate, and Google indexed a different URL as the canonical.
- It has little unique value compared with pages Google already holds.
- It carries a
noindexdirective, sometimes left over from staging. - It returns an error or a "soft 404," a page that says "not found" but returns a 200 status.
On top of that, the web keeps growing, much of it AI-assisted content. Google rations attention, so a new page on a young or weakly linked site waits longer than a new page on a site Google already crawls often.
How long indexing takes and what affects it
How long it takes Google to index a page ranges from about a day to several weeks, and Google publishes no fixed timeline. Its URL Inspection help says indexing "typically takes only a day or so, but can take much longer in some cases" (URL Inspection tool). Its recrawl guide says crawling "can take anywhere from a few days to a few weeks," and that "requesting a recrawl multiple times for the same URL won't get it crawled any faster" (Ask Google to recrawl your URLs).
What moves the needle:
Factor | Faster | Slower |
|---|---|---|
Site crawl frequency | Established site Google visits daily | New domain with few links |
Internal links | Linked from the homepage or a frequently crawled hub | Orphan page, buried deep |
External links | Linked from pages Google already crawls and indexes | No links, or links on unindexed pages |
Server health | Fast, stable responses | Slow responses, 5xx errors, timeouts |
Page value | Unique, useful content | Thin, duplicate or templated content |
Signals | Listed in the sitemap with an accurate | Missing from the sitemap, or |
Treat any tool or vendor promising instant Google indexing with caution. Google's own help says "Indexing is never instant, even when you submit a crawl request directly" (Page indexing report help).
How to check if a page is indexed
To check whether a page is indexed, use URL Inspection in Search Console for pages you own, and an index checker for many URLs or pages on other sites. A site: search gives a rough look but isn't proof.
- URL Inspection (Search Console help) shows whether the URL is on Google, the last crawl date, the canonical Google selected and any indexing issue. It only works on verified properties, one URL at a time.
- The Page indexing report in Search Console shows indexed and not-indexed counts for the whole property, grouped by reason. See the page indexing report explained.
site:search. Google's own site: operator docs say the list "is not always exhaustive" and that an indexed URL can show up "however it's not guaranteed."- Bulk index checkers query Google for each URL and record the answer. They're the practical option for hundreds of URLs, client sites or backlinks on sites you don't control. Our guide covers how to check if pages are indexed with each method.
Record the result with a date. Indexing changes over time, and a single check is a snapshot, not a verdict.
How to get a new page indexed
To get a new page indexed, make sure Google is allowed to index it, link to it from pages Google already crawls, list it in your sitemap, then request a crawl. Do it in that order, because a request for a blocked page wastes the request.
- Confirm the page is indexable. No
noindexmeta tag orX-Robots-Tagheader (Block indexing with noindex), not disallowed in robots.txt, returns a 200 status, and the canonical points to itself. - Make it worth indexing. Unique content that answers a real query. A thin or duplicate page will be crawled and dropped.
- Link to it internally from your homepage, a hub page or a recent post that Google crawls often.
- Add it to your XML sitemap with an accurate
lastmod. Google says it useslastmod"if it's consistently and verifiably" accurate (Build and submit a sitemap). - Request indexing with URL Inspection. Search Console has a daily quota for individual submissions. For more detail on every option, see how to submit a URL to Google.
- Re-check after a few days. If it's still missing, look at its status in the Page indexing report before requesting again.
A note on the Google Indexing API: Google's documentation says it "can only be used to crawl pages with either JobPosting or BroadcastEvent embedded in a VideoObject" (Using the Indexing API). It isn't a route for blog posts, product pages or backlinks, and Google says its spam policies apply to content submitted through it.
For many URLs at once, a push service sends Google a crawl signal per URL. The sensible version checks first and only acts on what's missing. FreshlyCited does exactly that: we check what Google has indexed, push the pages Google hasn't seen, then re-check on days 1, 3 and 7.
How to get an updated page re-crawled
To get an updated page re-crawled, change the page meaningfully, update its sitemap lastmod to the real edit time, and request a recrawl. Google keeps serving the version it last stored until it crawls again.
Updated pages are easy to forget. You refresh a pricing page, a comparison or a guide, and Google keeps showing the old title, old prices and old answers. Google's crawl demand includes staleness ("Our systems want to recrawl documents frequently enough to pick up any changes"), but popular pages get that attention first.
- Update
lastmodonly for real changes. Google's sitemap docs saylastmod"should reflect the date and time of the last significant update," and a copyright-year change doesn't count. - Request indexing once in URL Inspection. Repeating it doesn't help.
- Surface the update internally, for example a "recently updated" block on a crawled hub.
- Don't fake freshness. Bumping dates without changing content is a pattern Google and Bing both discourage.
Our walkthrough shows how to get Google to recrawl your site, including crawl budget on large sites.
Common 'not indexed' statuses and what they mean
The Page indexing report in Search Console groups not-indexed pages by reason. Some reasons are normal and need no action; others mean a page you care about is invisible.
Status in the report | What it means | Usually needs action? |
|---|---|---|
Discovered - currently not indexed | Google knows the URL but hasn't crawled it yet | Yes, if it lasts or affects many important pages |
Crawled - currently not indexed | Google crawled it and chose not to index it, for now | Yes, if the page matters |
Google sees it as a duplicate and you didn't declare a canonical | Sometimes | |
Duplicate, Google chose different canonical than user | Google ignored your canonical and picked another URL | Check it |
Points correctly to an indexed canonical | No | |
Page with redirect | The URL redirects elsewhere | No, if intentional |
URL marked 'noindex' | A | Only if unintended |
URL blocked by robots.txt | Googlebot isn't allowed to crawl it | Only if unintended |
Soft 404 | Looks like an error page but returns 200 | Yes |
Not found (404) / Server error (5xx) | The URL fails | Yes, for pages that should exist |
The two statuses that cause the most confusion have their own guides: crawled - currently not indexed is usually a page-value problem, while discovered - currently not indexed is usually a crawl-priority problem. If your whole site seems absent, start with why your website isn't showing up on Google.
Google notes the report's example list "is limited to 1,000 items" and "isn't guaranteed to show all URLs in a given status" (Page indexing report help), so for large sites, check the URLs you care about directly.
Why indexing now decides eligibility for Google's AI Overviews and AI Mode
Google indexing now decides whether a page can appear in Google's AI answers, because AI Overviews and AI Mode link only to indexed pages. Google's rule is simple: to appear as a link in AI Overviews or AI Mode, a page must be "indexed and eligible to be shown in Google Search with a snippet" (AI features and your website). Being indexed is the first step. Whether an AI answer cites your page still depends on quality, relevance and authority.
Google also says there are "no additional technical requirements" for AI features, and that "indexing and serving isn't guaranteed." In other words, there is no separate AI submission channel. The page Google stored is the page AI Overviews and AI Mode can draw on, so an update that hasn't been recrawled can't be reflected there yet. Google says Gemini can ground its answers in "content from the Google Search index" too (Google's common crawlers).
Bing is a free extra. Microsoft says Copilot's web answers use the Bing search service (Microsoft Learn). So for sites you verify by hosting a key file, FreshlyCited also sends your updated pages to Bing through IndexNow (an open "this page changed" notice that Bing and other participating engines accept; Google doesn't use it), at no extra credit cost. ChatGPT, Perplexity and other assistants use their own crawlers and search partners. We don't submit to them, and we don't claim to.
Indexing is the first step, not the last. Our guide to AI search optimization covers what happens after the page is in the index.
Every guide in this series
Each guide in this series takes one Google indexing problem and walks through what it means, how to diagnose it and how to fix it.
Guide | What it covers |
|---|---|
Every status in Search Console's Page indexing report, which to ignore and which to fix | |
A cause-by-cause checklist, from | |
Why Google crawled a page and passed on it, and how to make it worth keeping | |
Why Google postponed the crawl, crawl budget and server capacity | |
Five ways to submit a page, from URL Inspection to bulk pushes, and their limits | |
Getting new and updated pages crawled, with sitemaps, internal links and recrawl requests |
If you manage more pages than URL Inspection can handle, or links on sites you don't own, a routine helps: check every URL, push only the invisible ones, then re-check and keep a record. Check your own links free.

Written by